AI Labs  /  The Synthetic Intelligence Director
AI Labs · Flagship

One director. A crew of AI engineers.
One standard: the truth.

This is how Haventech builds with AI. A human director sets the mission, the rules and the final word. A crew of AI engineers from Anthropic and OpenAI does the work, checks each other, and turns every lesson into a rule the software enforces from then on. NetCentral is the proof: 436 releases in 97 days.

Talk to us: 312-432-4480Meet the crew
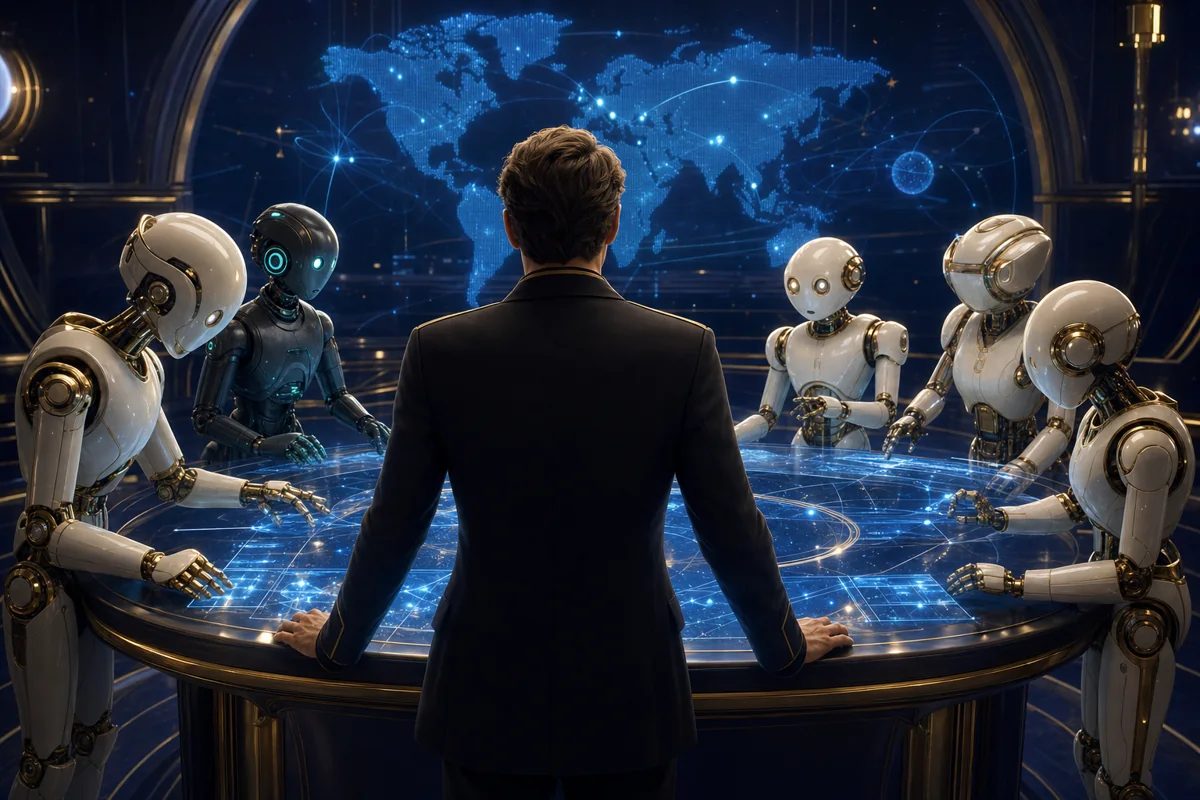
AI-generated illustration: a director seen from behind at a holographic console, working with a crew of droids
Illustration generated with OpenAI gpt-image-2 for this page.
436releases in 97 days
5,696automated tests on every change
222defects logged, each with its root cause
66standing rules learned from the director
The role

What a Synthetic Intelligence Director does

Synthetic intelligence is what you get when human judgment and machine capability are combined on purpose. Neither one runs alone. As Synthetic Intelligence Director, Jose M. Laboy doesn’t write the code. He directs the engineers who do: he decides what matters, sets the standard, and gives the final word. The AI crew researches, builds, tests and verifies. It is held to rules he set, and it is required to say so when something is wrong.

The director brings judgment

  • The mission: what matters on a live network, and why
  • The standards: what “done” and “true” mean here
  • Corrections that become permanent rules
  • Both gates: “go” to build, “deploy” to ship
  • Accountability to the people the work serves

The machine brings capability

  • Speed: research, code and tests in hours, not weeks
  • Recall: every rule, decision and lesson, every session
  • Verification: every claim re-checked against the real code
  • Stamina: the full test gate on every change
  • Candour: problems reported plainly, with the evidence
The operating model

Eight steps, two human gates, every time

Every change to NetCentral goes through the same flow. The AI does almost all of the work, and a person makes both decisions that matter.

Point

The director names a problem or a goal.

Investigate

Scout and design droids study the code and the screens and write a decision packet.

Verify

Keystone re-checks every finding against the real code and keeps only what holds.

Gate 1: Go

The director gets a short, verified list and decides in one word.

Human gate

Build

Keystone builds, tests first, on its own branch, through the full gate.

Second look

Sentinel and Contrarian, two models from two vendors, try to break it.

Record

Version, changelog, root cause and decision record are all written down.

Gate 2: Deploy

Only on the director’s word: snapshot, ship, verify live.

Human gate

The team advises. Claude judges. Jose decides.

Meet the crew

The Droids of NetCentral

Every AI engineer has a callsign, a job, a known blind spot, and a teammate who covers for it. Five run on Anthropic’s Claude. One comes from OpenAI on purpose, so the crew always gets a second opinion from a different maker. They advise and verify; the director decides. 30 decisions are on the record so far.

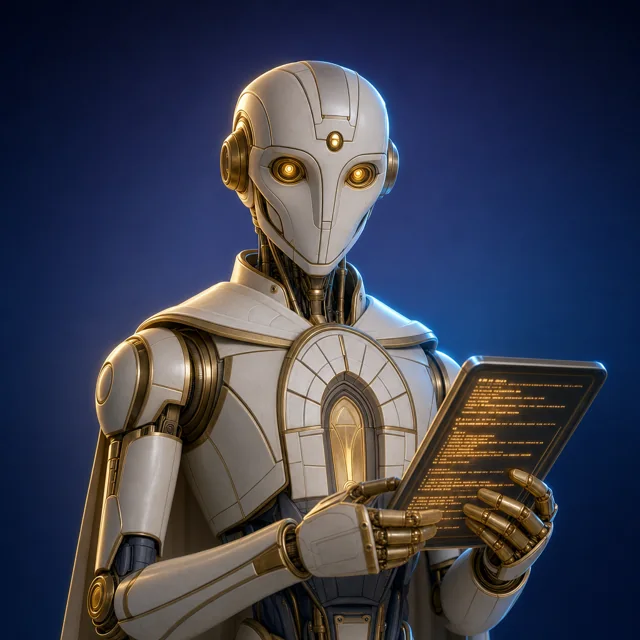
AI-generated portrait of Keystone, Command droid · final judge
K-1

Keystone

Command droid · final judgeClaude Opus 5.5 · Anthropic

Fact-checks every droid’s claim against the real code. The only unit cleared to touch the code. Builds tests first, merges, logs everything, deploys on command.

Blind spot: Cannot ship a thing without the director’s word. That is by design.
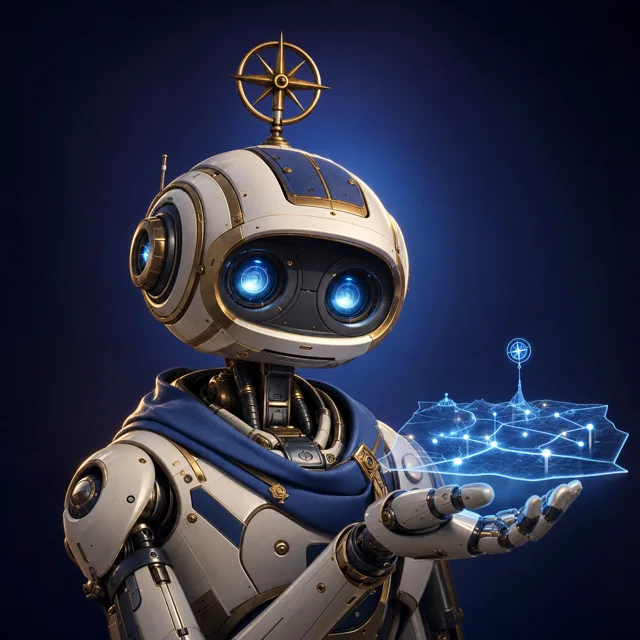
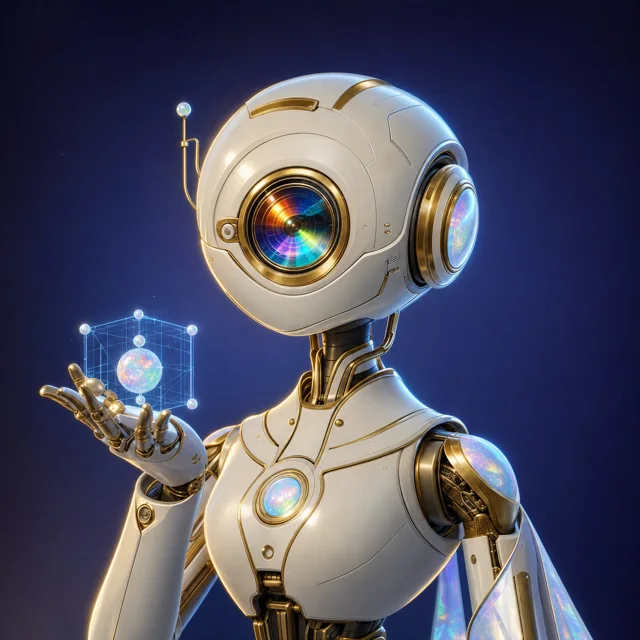
AI-generated portrait of Pathfinder, Scout · tech lead
PF-7

Pathfinder

Scout · tech leadClaude Opus 5.5 · Anthropic

Maps the whole codebase, audits one lens at a time (reliability, performance, tests, security), and turns it into a one-read decision packet with Path A and Path B.

Blind spot: Its facts hold up, but some of its proposed tests could never fail. Keystone catches those.

AI-generated portrait of Glint, Optics probe · design lead
GL-3

Glint

Optics probe · design leadClaude Opus 5.5 · Anthropic

Walks every screen like an operator at 3 AM with an alarm going off. Counts the clicks to the evidence. Measures alignment, contrast and cut-off data instead of eyeballing them.

Blind spot: Holds no login. It judges only the screens it is shown.

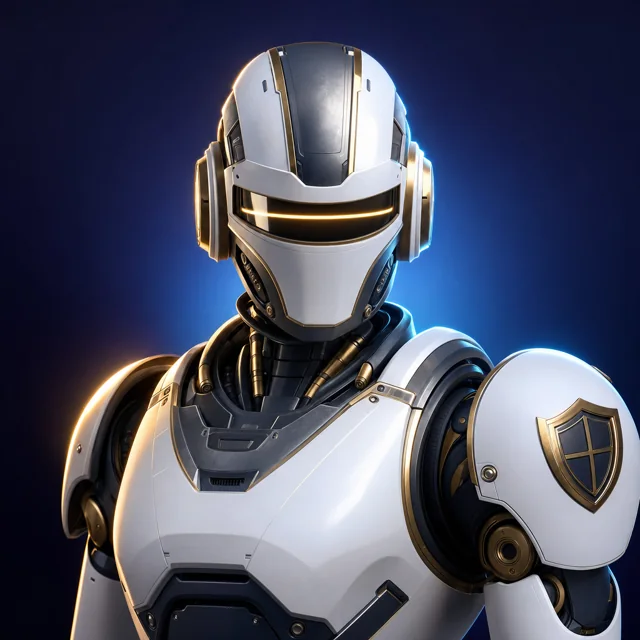
AI-generated portrait of Sentinel, Inspector · reviewer
SN-9

Sentinel

Inspector · reviewerClaude Opus 5.5 · Anthropic

Trusts nothing it is told and re-runs every test itself. Tries to break each new test to prove it can actually fail. Says “ready to merge” only when it would stake its name on it.

Blind spot: Thorough means patient: it re-runs the full gate every time.

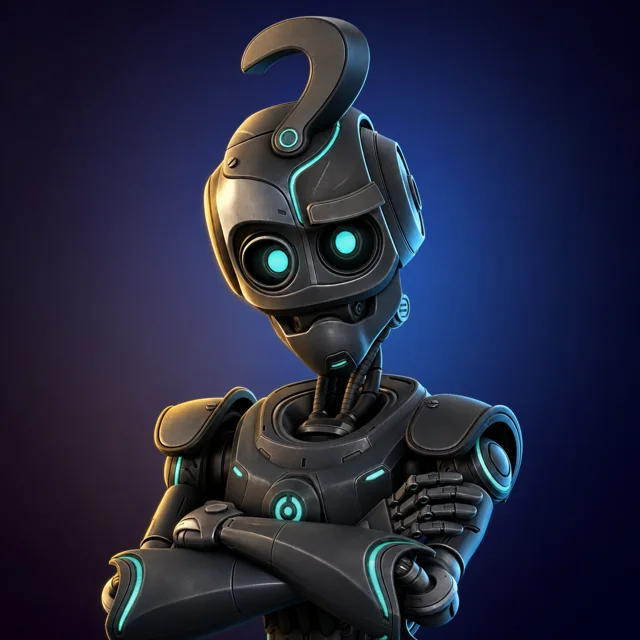
AI-generated portrait of Contrarian, Skeptic · second opinion
X-0

Contrarian

Skeptic · second opinionGPT-5.6 · OpenAI

Built by a different factory on purpose, so no change is ever approved by one model agreeing with itself. Never invents objections, and never softens one either.

Blind spot: Its memory is wiped after every mission, so it always starts with fresh eyes.

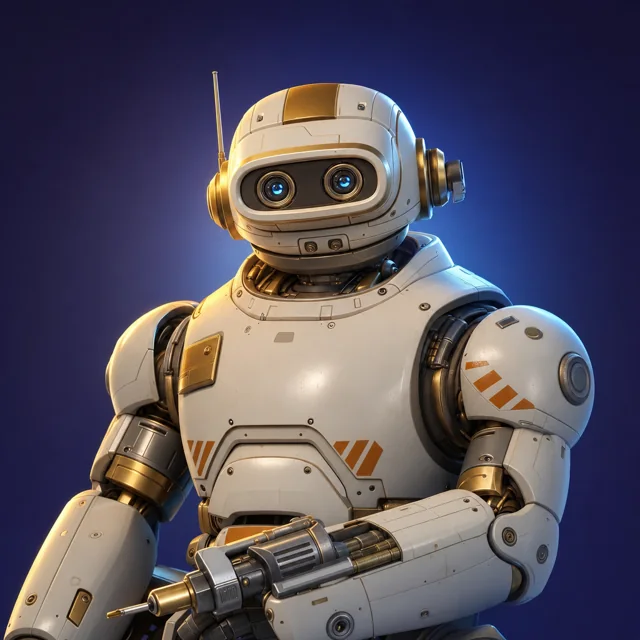
AI-generated portrait of Riveter, Builder · on reserve
RV-2

Riveter

Builder · on reserveClaude Opus 5.5 · Anthropic

Turned out 16 fixes on its first day, and every one passed review. It was then put on reserve when the director ruled that only one hand may touch the code.

Blind spot: Powered down by design. The droids advise; Keystone builds.

How judgment becomes reflex

The director teaches once. The system remembers for good.

This is the part people don’t expect. When the director corrects the AI, the lesson isn’t lost when the session ends. It becomes a standing rule, and where it can, an automated check that runs on every build. The crew carries 66 standing rules today, each one tied to a correction, a decision or an incident. The result is software that keeps getting better without forgetting what it learned.

Judgment becomes reflex Directorcorrects Rulerecorded Checkautomated Neverregresses
  • A correction is written down with the reason behind it
  • The rule is applied in every session that follows
  • Where possible, a test enforces it in every build
  • Each test is proven able to fail before it is trusted
  • 222 defects logged, every one with its root cause
The director: “Nothing is advice unless it is true.”

Recommendations must be verified

A vendor’s ‘recommended’ field is not a recommendation. Advice appears only when the evidence proves it applies to the exact device and version.

Now: Truth checks run in every build and refuse unverified advice.
The director: “Never leave the docs behind.”

Knowledge keeps up with the code

Every infographic and Help article is tied to the exact code it explains.

Now: When that code changes and the words don’t, the build turns red.
The director: “One unit, everywhere.”

Mb/s below 1,000, Gb/s above

kb/s beside Mb/s beside Gb/s on one screen made numbers hard to compare at a glance. One shared unit rule now formats every rate.

Now: An automated check refuses any hand-rolled rate maths.
The director: “Hidden means hidden.”

Hidden sites stay hidden on every surface

When the director hides a site, it disappears from every page, count, chart and AI answer. It is still collected, ready to reveal.

Now: A browser check walks dozens of pages on every build, looking for leaks.
The director: “An AI failure must say so.”

No AI button ever hangs or goes quietly blank

If an AI call fails or runs long, the screen says exactly that. It never looks like the feature is simply off.

Now: Every AI call a screen waits on goes through one guarded path, and a test fails if one doesn’t.
The director: “A guard that can’t fail is decoration.”

Every safety check is broken on purpose

Each new test is deliberately sabotaged once to prove it can go red. If it can’t, it isn’t a test.

Now: Sentinel does this on every review, before anything merges.

I never want to hide anything. Fully transparent, always and forever.

Jose M. Laboy · Synthetic Intelligence Director
The evolution

From 1.0 to 4.317.1 in 97 days

436 releases, 868 commits since version control began, and a test suite that has grown to 5,696 automated tests. A few of the milestones:

Jul 7, 2026

NetCentral 1.0

Six read-only sources, one correlation engine, and a grounded AI brief. Version 2.0 follows the same day.

Jul 9

3.0: Interactive Intelligence

Drill down from any number: a clickable health ledger explains the score, and every card explains itself.

Sep 10

Every change on the record

Version control, a verified backup and a rehearsed restore come first. From here, every change is tested, logged and reversible.

Sep 11

4.0: Ground Truth

An honest admission: version 3 looked right but was quietly wrong in ways no one could see. Version 4 rebuilt those parts, checked against the live network.

Sep 24

The estate reviewed

An AI ‘CCIE’ review measures every device against the estate’s own standard, with evidence and the exact fix.

Sep 28

The crew assembles

The droid crew is organised into the eight-step flow. The director rules that only one hand, Keystone’s, touches the code.

Oct 1

The truth audit

Six phases make every claim say exactly what its evidence says, and re-check every open finding.

Oct 2

The Briefing, read aloud

A morning state-of-the-network article, written from verified facts and spoken by an offline voice.

Oct 6

The Help Center

Help on every page, illustrated with real screens.

Oct 9

NetCentral News

An optional add-on: an animated news desk that presents the morning briefing.

Oct 10

The Infographic Library

53 posters, every fact on them computed from the live system.

Oct 11

Knowledge keeps up

Docs and posters tied to code. Drift turns the build red, and a badge tells the director what changed.

Even the briefing has a cast

Meet NetCentral News

NetCentral News is an optional add-on to NetCentral. Each morning the system writes a three-minute news show from the network’s verified facts and casts it like a real newsroom: the stories decide who reports. Claude writes the script, an offline speech engine gives each presenter a voice, and an animated desk lip-syncs every word. Every figure on air is checked against the live system before broadcast. The presenters are fictional. The characters were designed by Keystone and drawn with OpenAI gpt-image-2. Click anyone for their back story.

Trust by design

Bold with AI, careful with everything else

Read-only to the network

NetCentral reads more than a dozen trusted sources and never writes to a network device. Device configuration stays with humans, and a test enforces it.

Grounded and redacted

The AI answers only from facts the system already holds. Addresses, IDs, names and secrets are masked before anything leaves the box.

AI for operators only

Viewers can read the AI’s work but can’t prompt it. Every AI action has an owner, and every action is audited.

Verified on the live screen

A change isn’t done until it’s been seen working on the real page, in both directions: no false alarms, no false all-clears.

Reversible by default

Every deploy is preceded by a storage snapshot and followed by a live health check. A rollback point is always there.

Nothing hidden

Which AI did what is named, on this page and in the record. Transparency about method is a standing rule.

Full transparency

How this page was made

Written byKeystone (Claude Opus 5.5, Anthropic), from facts counted from the code at build time
Illustrated byOpenAI gpt-image-2, from prompts written by Keystone. Every image is AI-generated
Directed byJose M. Laboy, Synthetic Intelligence Director, who set the brief and authorized publication
Kept honest byA fact script: every number on this page is recounted from the record before each update

Figures as of October 12, 2026, NetCentral 4.317.1.

Let’s talk

Want to build with AI like this?

Call or email and a Haventech engineer will show you how a directed AI crew could work for your business. Mon – Fri, 6:30 AM – 5:00 PM.